What Is a Linear Model?
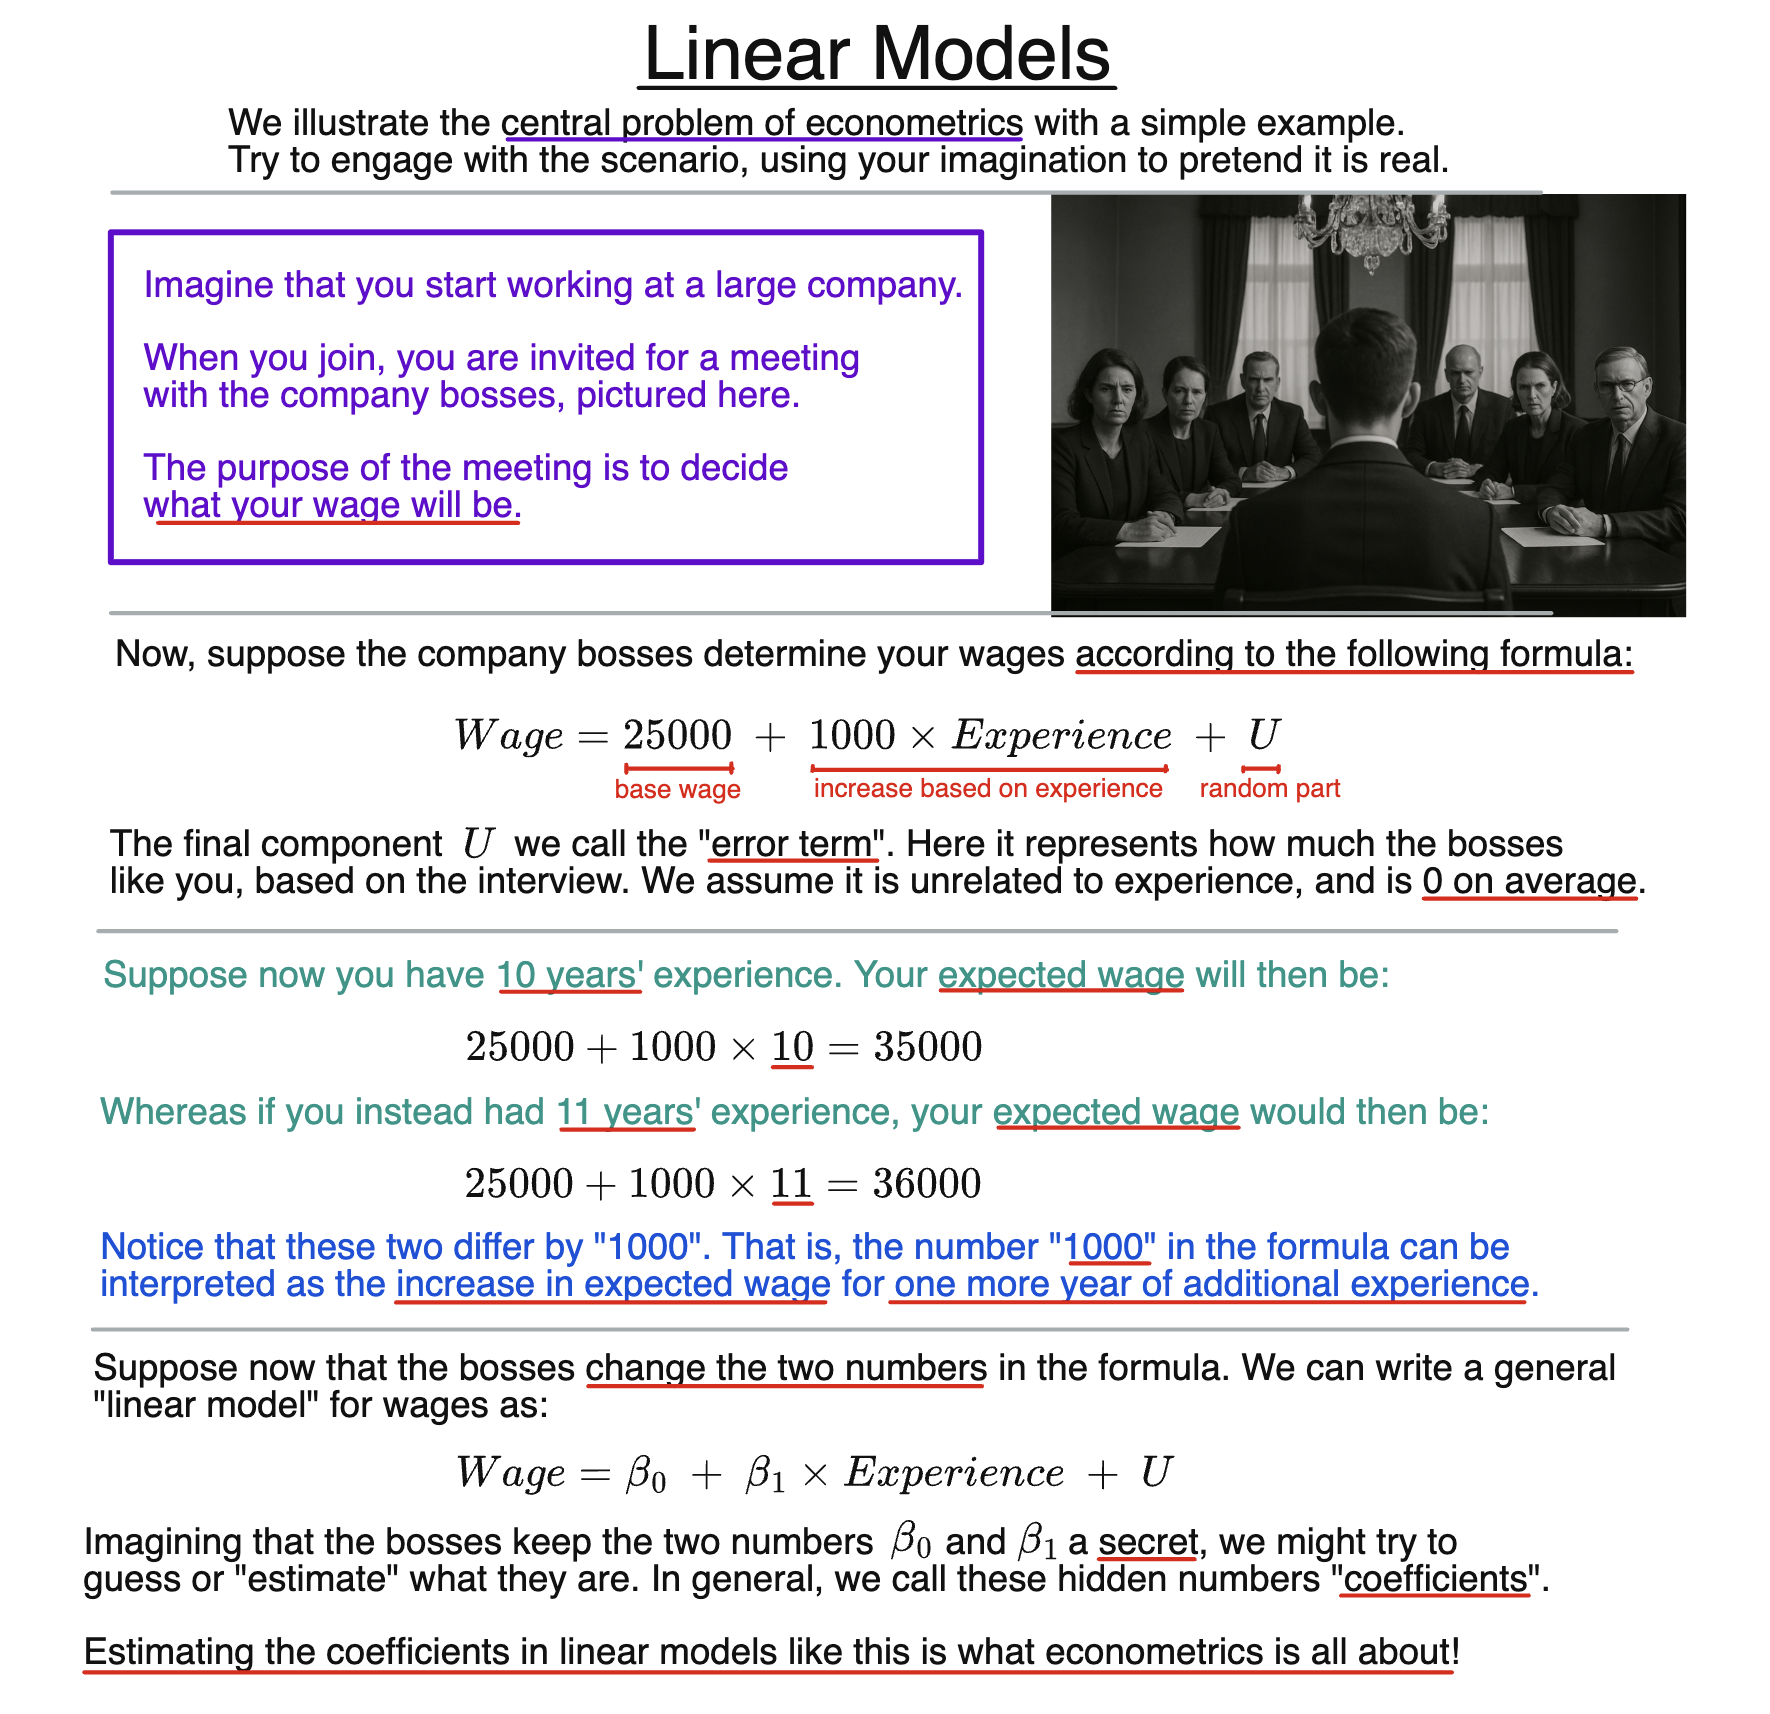
This slide and those that follow it in this section develop a single, rather fanciful example in some detail. In these accompanying articles, we instead develop things in a more general way.
A linear model describes how one variable is related to one or more other variables.
In the simplest case of interest, we have one dependent variable $Y$, one independent variable $X$, and an error term $U$. We write
$$Y=\beta_0+\beta_1X+U.$$
This may be thought of in various ways: for instance, as a literal formula by which $Y$ is partly determined by $X$, as in the slide above; as a way of predicting $Y$ based on $X$; as expressing a causal relationship between $Y$ and $X$; or even just as a “linear approximation” of some more complicated relationship between them.
The mathematical assumptions we’ll introduce later will help pin down which of these interpretations are appropriate.
In addition to our variables of interest, $Y$ and $X$, our model contains three other important components.
The coefficient $\beta_0$ is the intercept. It gives the value of $Y$ associated with $X=0$, before allowing for the error term $U.$
The coefficient $\beta_1$ is the slope. It tells us how much $Y$ changes when $X$ increases by one unit, again disregarding changes in the error term $U.$
Finally, we have this error term $U$ itself. Essentially, this represents any other factors affecting $Y$ that are not represented explicitly by $X.$
As we’ll see, this error term will cause us no end of problems – largely because, unlike $Y$ and $X$, we can never observe it directly.
Interpreting the Coefficients
Suppose, for example, that
$$Y=30+4X+U.$$
If the error term is $0$ on average for every value of $X$, then when $X=10$, the expected value of $Y$ is
$$30+4(10)=70.$$
If instead $X=11$ under the same conditions, the expected value is
$$30+4(11)=74.$$
Notice that the difference is $4.$ So, the interpretation of the slope coefficient is:
For each one-unit increase in $X$, the expected value of $Y$ increases by $4.$
This is worth learning to state precisely – not least because many exam questions ask about exactly this sort of thing.
The intercept has a different interpretation. It tells us the expected value of $Y$ when $X=0.$ In this example, that value is $30.$
Whether this interpretation is economically interesting depends on the context. Sometimes $X=0$ is a meaningful possibility; sometimes it is not. For instance, if $X$ is your age or your height, imagining that $X=0$ becomes rather silly.
Generally in econometrics, we are often rather less interested in $\beta_0$ than in slope coefficients like $\beta_1.$
The Error Term
Real-world relationships are rarely completely determined by a single observed variable.
For example, in the simplified example in the slide, wages depend not only on experience, but also on how much a worker is liked by the bosses.
In the real world, wages might depend on these factors, but also on education, ability, industry, location, luck, and many other things.
If we look at a model that includes only experience explicitly, these other influences end up in the error term $U.$
As we’ll see, much of econometrics consists of worrying about a possible relationship between the error term and other variables, such as $X$, that are included in the model.
The Coefficients Are Unknown
In practice, the coefficients $\beta_0$ and $\beta_1$ are usually unknown to us.
That is, we generally start from the position of believing that a linear model describes the relationship between two variables, but not knowing the numerical values of the intercept and slope.
This creates the central problem of econometrics:
How can we estimate these unknown coefficients?
Over the next few slides, we’ll answer this question by introducing the method of “linear regression”. Once this matter is settled, we’ll then write our estimates of the unknown coefficients as
$$\hat\beta_0\qquad\text{and}\qquad\hat\beta_1.$$
The “hats” on the top are very important – and not just for decoration. $\beta_0$ and $\beta_1$ are the true coefficients in the model, whereas $\hat\beta_0$ and $\hat\beta_1$ are just our estimates of them based on the sample.
If you don’t keep these two concepts separate, the technical work we’ll do later will make very little sense!
Background
Understanding Econometrics is completely free to use, and always will be.
If you found the site useful and would like to help me keep adding new material, please consider buying me a coffee! Buy me a coffee ☕