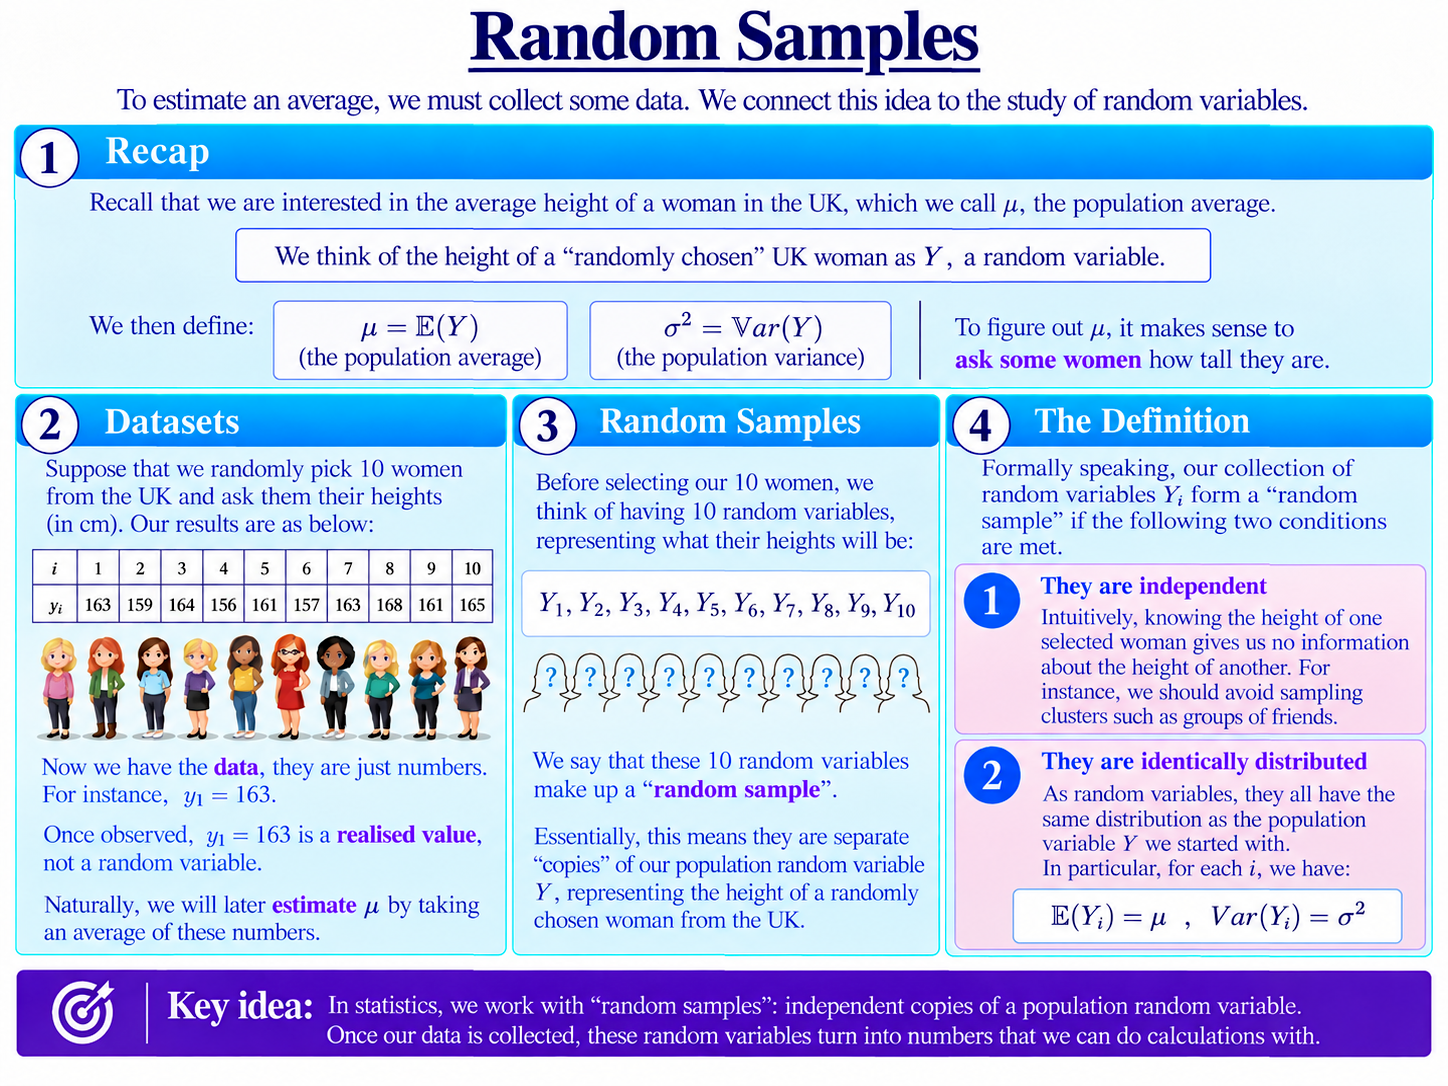
What Is a Random Sample?
A random sample is a collection of independent random variables, all with the same distribution.
For example, suppose we are interested in the average height of a woman in the UK. Since we do not have enough information to calculate this using maths alone, it makes sense to ask some women their heights and use these data to form an estimate.
As we saw on the previous page, in statistics we think of selecting a woman and asking her height in the same way that we think of rolling a die.
In particular, we define a random variable equal to the outcome of randomly selecting a woman from the population and recording her height. We call this our population random variable, denoted here by $Y$.
The population mean we are looking for is then modelled as
$$\mu=\mathbb{E}(Y).$$
So far, so good. But in practice, to figure out $\mu$, we would usually not ask just one woman, but many.
If we plan to ask $n$ women their heights, then before collecting our data we think of the responses we will get as $n$ random variables:
$$Y_1,Y_2,\dots,Y_n.$$
This collection forms a random sample if two conditions are met.
1. They Are Independent
The first condition is that $Y_1,Y_2,\dots,Y_n$ are independent.
Intuitively, knowing the height of one woman in our sample should give us no information about the heights of the others.
This relates to the way we collect our data. For instance, we should avoid sampling clusters such as groups of friends, whose characteristics may be related.
Each observation should instead represent a separate random selection from the population.
2. They Are Identically Distributed
The second condition is that $Y_1,Y_2,\dots,Y_n$ are identically distributed.
They should all be essentially separate “copies” of the same population random variable $Y$, corresponding to selecting a single woman at random from the UK population.
So, for every $i$, $Y_i$ has the same distribution as $Y$. Of course, they therefore all have the same distribution as each other too!
In particular,
$$\mathbb{E}(Y_i)=\mu,\qquad \operatorname{Var}(Y_i)=\sigma^2.$$
It should not matter whether we are talking about the first woman we plan to ask, the fifth, or the last. We are supposed to be using the same random selection process each time.
For example, it would be a problem if women later in our sample were systematically different from women selected earlier — perhaps because we collected different parts of our data in different places or at different times. For instance, if we collected our sample at different times of day in a rough neighbourhood, it might be that taller women feel more confident in being out and about later at night. This would mean that later random variables in our sample tend to be bigger than earlier ones.
Together, independence and identical distribution are often abbreviated to IID. So we may simply say that a random sample consists of $n$ IID random variables.
What Would Random Sampling Look Like in Practice?
To illustrate what these assumptions mean, imagine a rather fanciful ideal experiment.
Suppose a census provided us with a complete list of every woman in the UK, and assigned each woman a number, from $1$ to $N$.
We could generate a random number from $1$ to $N$ with a computer, find the corresponding woman, and record her height. We could then continue to repeat the process until we had collected all our observations.
If we generate each number independently in exactly the same way, this is a particularly clean instance of IID sampling.
Notice that technically we would be sampling with replacement: after a woman had been selected once, her number would remain available. In principle, then, we could select the same woman twice!
Unfortunately, real-world data are rarely collected quite this neatly. We may not have a complete list of the population; some people may be easier to reach than others; some may refuse to answer; and we may accidentally sample people in related groups – for instance, if they convince each other to respond to a survey.
We see here that the IID assumptions are partly assumptions about the way our data have been collected. That is, they give us a clean probability model for a real-world process representing good data collection – although in reality things are usually somewhat messier. However, later on we will also use them directly in mathematical proofs.
Random Samples and Observed Data
Our random sample
$$Y_1,Y_2,\dots,Y_n$$
is different from the dataset
$$y_1,y_2,\dots,y_n$$
that we obtain after actually collecting the data.
Before collecting the data, the $Y_i$ are random variables. We do not yet know what values they will take.
Suppose, for instance, that we select $10$ women and obtain the heights
$$163,\ 159,\ 164,\ 156,\ 161,\ 157,\ 163,\ 168,\ 161,\ 165.$$
Once observed, these are just numbers. We may write them as
$$y_1,y_2,\dots,y_{10},$$
where, for example,
$$y_1=163.$$
So $Y_1$ is a random variable representing the height we will obtain before we collect our data, whereas $y_1=163$ is its realised value afterwards.
Generally, we should try to distinguish the two by using capital letters for random variables and lower-case letters for ordinary observed numbers – though not everyone sticks to this very thoroughly!
Background
Understanding Econometrics is completely free to use, and always will be.
If you found the site useful and would like to help me keep adding new material, please consider buying me a coffee! Buy me a coffee ☕